AI news, November 6, 2026: Claude Personal Finance, GPT-6 Cyber and Gemini Omni 1.2 Flash
Short answer: The main story of November 5: Anthropic starts Personal Finance in Claude (beta, US, read-only), OpenAI launches the cyber model GPT-6 Cyber for selected customers and Google releases Gemini Omni 1.2 Flash, with video up to 15 seconds and 30% lower costs. Among the coding tools, live apps in Cursor and remote agents in Antigravity stand out. Below, each topic comes with what it means and where it comes from.
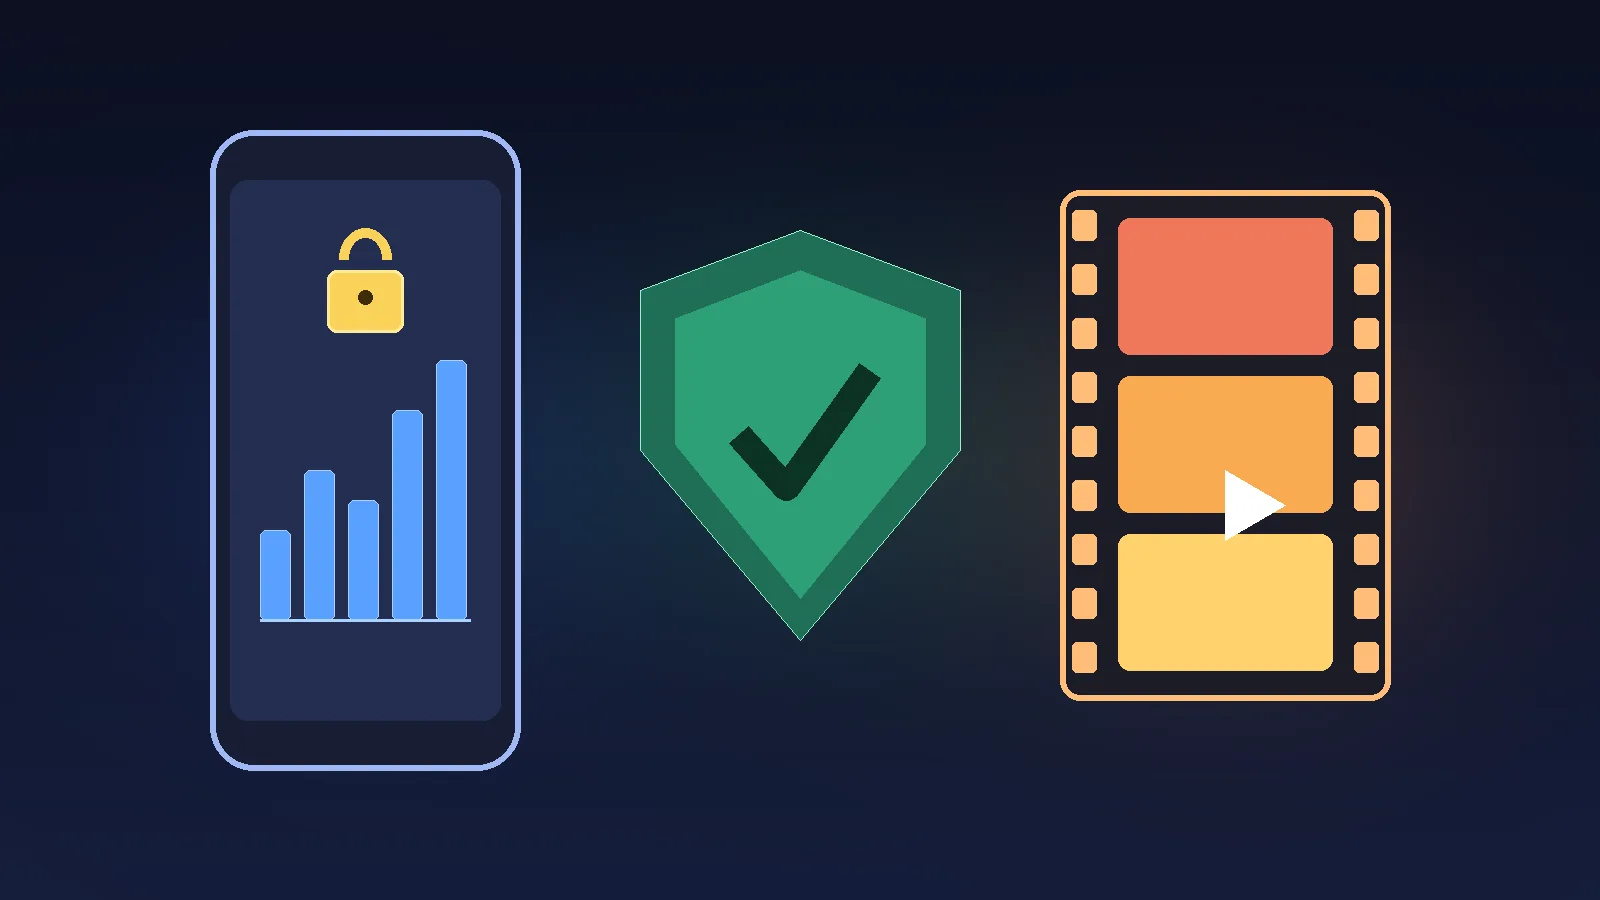
Illustration by Claude (AI), drawn with code: a phone with a bar chart and lock (Personal Finance), a shield (GPT-6 Cyber) and a film strip (Gemini Omni).
Claude gets Personal Finance in beta: questions about your own accounts, read-onlyConfidence: high (Anthropic's own announcement; rollout per plan according to TestingCatalog)
Anthropic announces Personal Finance in Claude on X, a beta feature for the US. Users connect accounts of their choice and can ask Claude questions about balances and transactions. The feature is read-only: Claude does not move money. The announcement drew about 29,000 likes. According to TestingCatalog the rollout goes to Pro, Max and Ultra users in the US. In a follow-up post Anthropic says there will be no ads or sponsored recommendations and that the feature is not meant as investment advice. Nothing has been announced for Europe.
Which connections are supported and how the data is stored is not in the posts; the official help page may say. Claude, the model writing this briefing, is a product of Anthropic. We therefore only relay what the company itself reports.
What this means: for US users an assistant arrives that can look into their own bank data, within clear limits (read only, no advice). For Dutch users nothing changes for now. Anyone who wants to use it has to check for themselves which data is shared.
Sources: @claudeai op X (Personal Finance) · @claudeai op X (geen advertenties) · @testingcatalog op X (uitrol)
OpenAI introduces GPT-6 Cyber; Factory offers a simulated state-level attack and Private Safety Processing arrivesConfidence: high (GPT-6 Cyber, Wargames, Private Safety Processing: own announcements), medium (Lockdown Mode and OpenSSH: media reports, patch status unknown)
OpenAI launches GPT-6 Cyber on X, a model for security research. According to OpenAI the model also powered the Linux kernel research of November 4. It is available to selected Daybreak Red customers and access will grow later. OpenAI names Mozilla, Palo Alto Networks, Calif and Cisco as users. The post drew more than 15,000 likes. Andrew Curran writes that the model is stronger than Astra and that Daybreak Red is a new group for defenders of critical infrastructure; that is his reading.
With Wargames, Factory offers a simulated state-level attack on a company's infrastructure at Factory's expense. Droids then help with the fixes for free. OpenAI also announces Private Safety Processing: related API requests are checked for safety without prompts or responses being stored; the records stay in the customer's environment.
Two smaller reports carry less certainty. Researchers reportedly found a flaw in HTML previews that allowed ChatGPT's Lockdown Mode to be bypassed, enabling silent data exfiltration. Whether it has been patched since is not in the post. BleepingComputer also reports an OpenSSH flaw that lets attackers log in to Linux accounts with a disabled password; details and versions are missing from the post.
What this means: the cyber model behind the kernel pipeline is now a product, but with limited access. That keeps the dual-use debate going (the same model helps defenders and attackers). Administrators of Linux servers do well to follow the OpenSSH report. Background is in our overview of AI and cybersecurity and in our article on OpenAI's Linux pipeline.
Sources: @OpenAI op X (GPT-6 Cyber) · @AndrewCurran_ op X (duiding) · @factory op X (Wargames) · @OpenAIDevs op X (Private Safety Processing) · @TheHackersNews op X (Lockdown Mode) · @BleepinComputer op X (OpenSSH)
Gemini Omni 1.2 Flash makes video up to 15 seconds and 30% cheaper; Meta, Mistral and Perplexity follow with agents and avatarsConfidence: high (Google, Meta, Mistral: own announcements), medium (Perplexity Teammates: via TestingCatalog)
Google presents Gemini Omni 1.2 Flash, the updated video model. Clips run up to 15 seconds, editing happens conversationally, consistency is better and costs are 30% lower. The model is also in AI Studio and the Gemini API. According to Google a draft at 360p or 720p costs $0.07 per second, after which you scale up to 1080p or 4K. The Gemini app reports a rollout to all Google AI subscribers. Prices and limits per plan are not in the posts.
Meta rolls out Muse Realtime Avatar in the Muse app in the US: realtime avatars on top of Muse Realtime Voice. Mistral introduces managed agents and apps in Mistral Studio, with workflows, enterprise connections, observability and evaluations. Perplexity is said to be rolling out Teammates, proactive agents for Max subscribers on the web with an isolated environment, skills and memory; that report comes from TestingCatalog and not from Perplexity itself.
What this means: video models now compete on price per second and on editability, not only on image quality. The 30% price cut is a Google claim; anyone making video for work does best to compare the price per second at the format they need.
Sources: @Google op X (Gemini Omni 1.2 Flash) · @OfficialLoganK op X · @AIatMeta op X (Muse Realtime Avatar) · @MistralAI op X (Studio) · @testingcatalog op X (Perplexity Teammates)
Cursor builds live apps, Antigravity gets remote agents, Devin Review 2.0 is cheaper and Copilot Fusion picks the model itselfConfidence: high (own announcements; performance claims not independently tested)
Cursor lets users build and share live apps through a link: you describe the tool, Cursor builds it, sets up a database, runs security checks and deploys. One-click deploy runs on Vercel, which also posted about the feature itself. Google Antigravity rolls out remote agents this week: tasks run in separate cloud VMs and you can approve permissions from your phone.
Cognition announces Devin Review 2.0 for pull request reviews, up to 5 times cheaper and 1.5 times faster. Vercel Schedules is in public beta: agents and apps schedule their own tasks, statically in code or dynamically at runtime. GitHub has Copilot Fusion route and orchestrate models in three variants (Single, Cascade and Critique); users only choose the effort level. A 30% discount applies until November 30. Supabase shows how to add your own MCP server to your app, with an OAuth 2.1 server in Supabase Auth.
What this means: the tools for building with agents are moving towards cloud environments where tasks continue without an open laptop. The speed and price claims from Cognition and GitHub are their own figures without independent testing. More background is in our overview of Cursor and in our overview of MCP servers.
Sources: @cursor_ai op X (live apps) · @antigravity op X (remote agents) · @cognition op X (Devin Review 2.0) · @vercel op X (Schedules) · @github op X (Copilot Fusion) · @supabase op X (MCP-server)
EmbeddingGemma 2 gets a tech report, Hugging Face brings ML Intern to Slack and NVIDIA shows Nemotron for agentsConfidence: high (Google and Hugging Face: own announcements), medium (NVIDIA), low (Verda: a single post)
Google publishes the tech report for EmbeddingGemma 2, an open multimodal embedding model of 740 million parameters: one representation for text, code, image, audio and video, with architecture and ablations. Hugging Face makes the open-source ML Intern available as a Slack bot for your own workspace, to evaluate models, build datasets and fine-tune models. At BoxWorks 2026 NVIDIA showed how the Nemotron models can be used for agents with enterprise context and tools; that post is from NVIDIA itself and contains few details.
A small EU cloud, Verda, reports Kimi K3.1 Pro in the preview of Verda Inference. That is one post with two likes and therefore unconfirmed.
What this means: for anyone building search systems or their own agents on their own hardware, a small open embedding model that handles several media is a practical development. How the performance compares with other models will only show in tests. More about embedding models is in our article embedding models compared.
Sources: @googlegemma op X (EmbeddingGemma 2) · @huggingface op X (ML Intern) · @NVIDIAAI op X (Nemotron) · @shipfrontierai op X (Verda)
Analyst Dan Ives: midterms slow AI data centre construction, SemiAnalysis sees supply as the limit until 2027Confidence: medium (analyst forecasts), low (GPU lifetimes: a single account)
According to a post by StockMKTNewz, analyst Dan Ives expects the midterm results to slow the construction of AI data centres. Big Tech's capex growth peaks in 2027, he says, earlier than his previous estimate of 2028-2029. That is his forecast, which we cannot test. After the quarterly figures of Advantest and Teradyne, SemiAnalysis reports that the market for chip test equipment is growing on AI compute and that supply, not demand, is the brake until 2027.
An analyst account also compares the assumed lifetime of GPUs: Nvidia says eight years or more, neoclouds book six years and their banks use three to four. That comparison has not been worked through; the post has 39 likes.
What this means: the difference in depreciation between providers and financiers shows how uncertain the bill for the AI build-out is. For readers following the demand for energy and chips, these are signals to compare with the data centre capacity that is actually delivered. More is in our article on the race in chips and hardware and in our overview of AI and energy.
Sources: @StockMKTNewz op X (Dan Ives) · @SemiAnalysis_ op X (testapparatuur) · @nodiligence op X (levensduur GPU's)
Still unconfirmed: METR and Anthropic, GPT-6.2 Astra, a price rise for Gemini 4 Argon and complaints about Grok Bot limitsConfidence: low to medium (no confirmation from the companies themselves)
Andrew Curran reports on X, citing METR, that Anthropic has an internal model that was ready last month and scores above 50% on every benchmark tested, and that Anthropic would have reached the 2x acceleration threshold in its own Responsible Scaling Policy. The METR report itself has not been read; this comes via one account and Anthropic has not reported on it in the posts we found. Claude is a product of Anthropic; we therefore include this only as unconfirmed.
One account claims GPT-6.2 Astra will not appear on November 5 and may come Friday, because OpenAI never releases after 11:00 Pacific and does not follow a cyber model with a new model shortly afterwards. That is a rumour without a source at OpenAI. Another account says Gemini 4 Argon goes from $2/$10 to $4/$20 per million tokens on December 1 and that Gemini 3.8 Flash doubles on January 1; that post has one like and is not confirmed by Google.
Elon Musk keeps promoting Grok Bot with several short posts, including a video of the bot calling a dentist; there is no new price or limit information. A tool maker advertises an alternative because Grok Bot would be unusable due to usage limits; that is a commercial claim by a third party with 73 likes.
What this means: these reports are useful to follow but not yet to act on. Anyone who needs prices or release dates for planning does better to wait for confirmation from the company itself.
Sources: @AndrewCurran_ op X (METR) · @Mr_Salio op X (GPT-6.2 Astra) · @iamdeepoo op X (Gemini 4 Argon) · @elonmusk op X (Grok Bot) · @rerun_build op X (limieten)
Primary sources: Claude op X · OpenAI op X · Google op X · Cursor op X · Antigravity op X